RAG development services

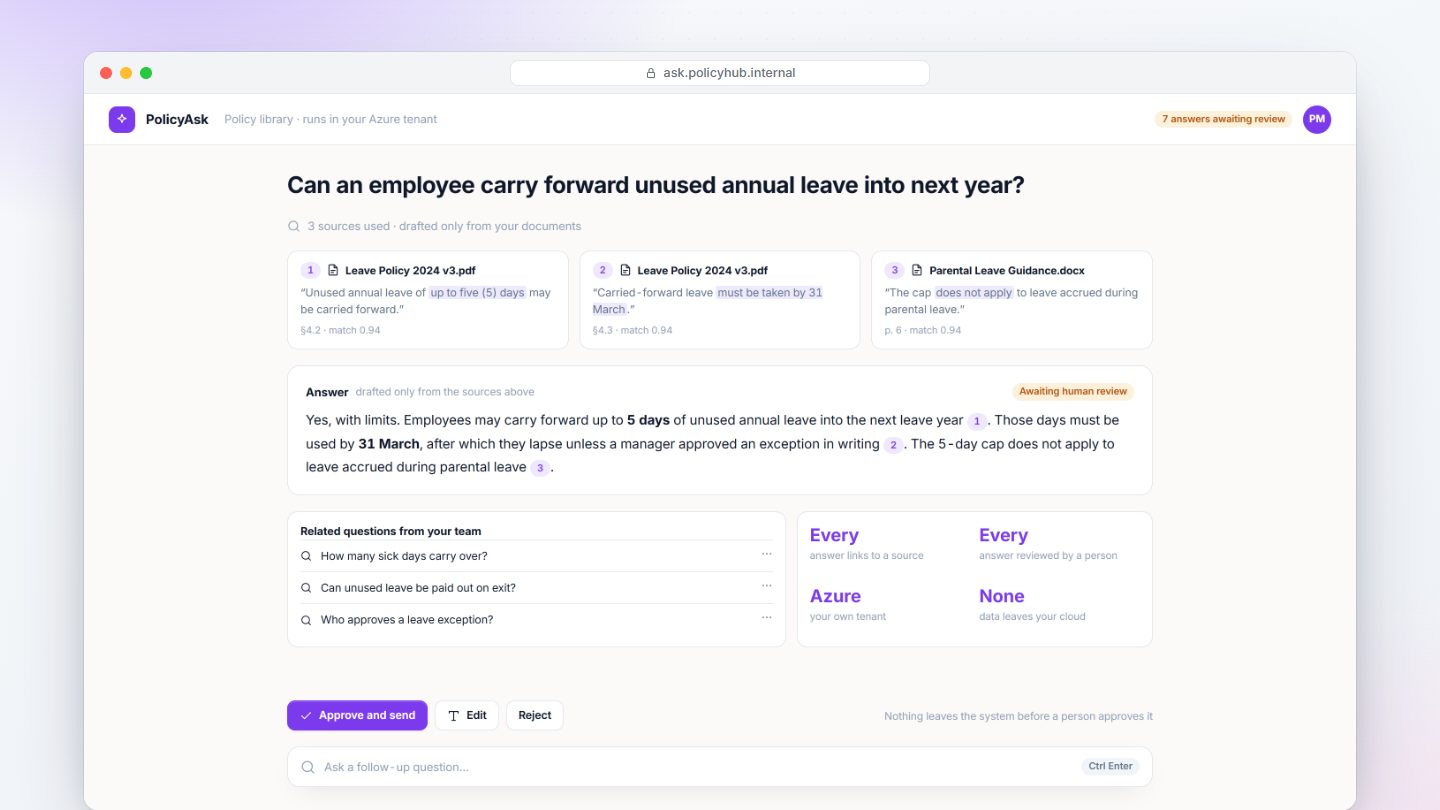
Retrieval-augmented generation that answers from your documents, cites its sources and runs inside your cloud.

What you get

  • RAG pipelines
  • Knowledge assistants
  • Evaluation and monitoring

Last updated

The problem

A generic chatbot can sound certain and be wrong, and you cannot check it.

RAG fixes the cause. Before the model writes anything, the system retrieves the relevant passages from your documents. The answer is built from those passages, so each claim can be traced back to its source.

What we build

What we build

  • 01

    RAG pipelines

    Retrieval, grounding and generation built into your architecture.

  • 02

    Knowledge assistants

    Question-and-answer over your own policies, documents and records.

  • 03

    Evaluation and monitoring

    Measured accuracy, guardrails and review points that keep answers reliable.

How it works

Retrieve, ground, generate, cite.

  1. 1 Retrieve

    Find the right passages in your own documents.

  2. 2 Ground

    Limit the answer to what was found.

  3. 3 Generate

    Draft the response with the model you chose.

  4. 4 Cite

    Show which source supports each claim.

  5. 5 Human checkpoint

    A reviewer approves before anything is sent or saved.

Tools

Tools behind the work

We choose tools for each project, not the other way round.

  • LangChain
  • Vector databases
  • Azure OpenAI
  • OpenAI
  • Anthropic Claude
  • Open-source models

Proof

FAQ

Questions, answered.

What is retrieval-augmented generation (RAG)?

RAG connects a language model to your own documents. The system finds the relevant passages first, writes an answer from them and cites its sources. That keeps answers tied to your data instead of the model's memory.

How is RAG different from fine-tuning a model?

RAG retrieves relevant information when a question is asked, so you can use new documents without retraining the model. Fine-tuning changes the model itself. Many production systems start with retrieval.

How do you reduce wrong answers?

We ground answers in retrieved sources, require citations, measure accuracy and add human review for consequential decisions.

Can RAG run inside our own cloud?

Yes. We deploy RAG pipelines inside your cloud and security boundary, on the model provider you choose.

Related

Contact

Have documents people struggle to search?

Tell us what you have. We will show how RAG could work for it.

What you can expect

  1. A reply within one business day.
  2. A short call to understand your project.
  3. A clear proposal, without a long sales process.